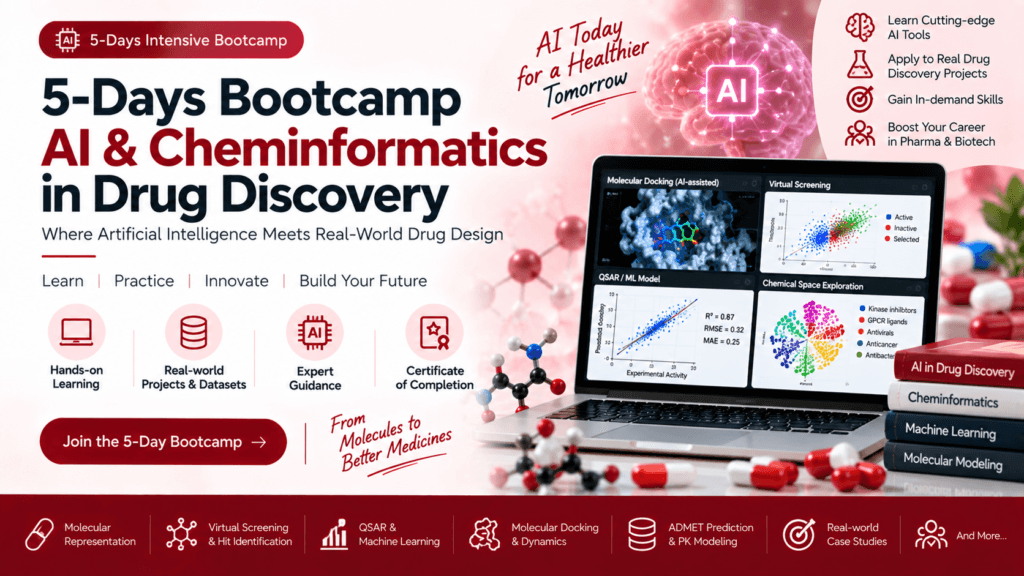
5-Days Bootcamp AI & Cheminforma-
tics in Drug Discovery
- Understand the modern drug discovery pipeline
- Handle chemical data (SMILES, SDF, descriptors)
- Perform virtual screening & docking
- Build QSAR models and predict ADMET properties
- Apply AI-driven generative models for novel molecule design
- Create an end-to-end workflow for lead compound identification
.
.
Educator
Shivani Singh

Difficulty
Beginner to Expert

Mode
Live Session

Language
English
AI & Cheminformatics in Drug Discovery
Mode – Live Session
Certificate Provided
5 Days
Time 7:00 PM IST
Start Date 25 Sept
Last date 24 Sept
Bootcamp Outcomes
- By the end of this bootcamp, you will:
- Develop your own cheminformatics pipeline
- Screen, dock, and analyze candidate molecules
- Apply machine learning & AI to predict molecular properties
- Present a complete mini drug discovery project
Day-1
Introduction to Cheminformatics with RDKit
Topic: The drug discovery pipeline and chemical data handling
Overview of the modern drug discovery process, from target identification to lead optimization.
Introduction to chemical data and molecular representations (SMILES, SDF), and physicochemical descriptors.
Hands-on:
Install Python, Miniconda, and libraries (RDKit, Pandas, NumPy, Matplotlib, Jupyter Notebook).
Learn how to use Jupyter Notebook and standard Python data science libraries.
Read and write chemical files with RDKit.
Calculate molecular properties (molecular weight, logP, polar surface area).
Implement Lipinski’s Rule of Five to filter drug-like molecules.
Project Task: Select a target protein and download a relevant compound dataset from PubChem or ChEMBL.
Day-2
Virtual Screening and Compound Visualization
Topic 1: Exploring Chemical Space
Techniques for screening large chemical libraries (similarity searching, clustering).
Hands-on:
Generate molecular fingerprints (e.g., Morgan fingerprints).
Perform similarity searches to identify drug-like molecules.
Topic 2: Molecular Visualization
- Visualizing small molecules and proteins to understand 3D structure and interactions.
Hands-on:
Install and use visualization tools (PyMOL or UCSF Chimera).
Generate 3D conformers for molecules using RDKit.
Visualize molecules from the Protein Data Bank (PDB) in PyMOL.
Project Task: Use RDKit to generate 3D conformers for compounds identified on Day 1.
Day-3
Molecular Docking with Open-Source Tools
Topic 1: Introduction to Protein-Ligand Docking
Principles of structure-based drug design and docking theory.
Hands-on:
Prepare a protein target and a ligand for docking.
Use AutoDock Vina to predict ligand binding poses.
Topic 2: Analyzing Docking Results & Workflows
Interpreting docking scores and binding poses.
Incorporating docking into automated workflows.
Hands-on:
Analyze docking poses and scores in PyMOL or UCSF Chimera.
Set up a basic cheminformatics pipeline in KNIME.
Project Task: Perform docking of selected compounds against the target protein.
Day-4
Machine Learning in Drug Design
Topic 1: QSAR Modeling with scikit-learn
Introduction to Quantitative Structure-Activity Relationships (QSAR).
Using ML models to predict molecular properties.
Hands-on:
Generate molecular descriptors with RDKit.
Train a machine learning model (Random Forest Regressor) in scikit-learn.
Topic 2: Predicting ADMET Properties
Importance of ADMET (Absorption, Distribution, Metabolism, Excretion, Toxicity) in drug discovery.
Hands-on:
Predict ADMET properties with ADMETLab.
Integrate ADMET prediction into QSAR workflow.
Project Task: Build a QSAR model and predict ADMET properties for docking hits to identify top candidates.
Day-5
AI-Driven Compound Generation & Wrap-Up
Topic 1: Generative AI for Molecules
Introduction to deep learning for drug-like molecule generation (SMILES-based models).
Hands-on:
Use a pre-trained generative model for molecule design.
Filter generated molecules for drug-likeness using RDKit.
Topic 2: Putting It All Together
Review of the full drug discovery workflow and future of AI in the field.
Hands-on:
Combine all steps into a comprehensive Jupyter Notebook.
Present project results: identified lead compounds and selection rationale.
Educator – Shivani Singh
Shivani Singh is a PhD scholar in Computational Biology & Bioinformatics at Sharda University, currently working as a Bioinformatics Educator. She specializes in protein structure prediction, molecular docking, and AI-driven drug repurposing. With an MSc in Bioinformatics, she has conducted hands-on workshops in molecular docking, MD simulations, and bioinformatics pipelines. Her teaching combines research experience with practical skills in structural bioinformatics, cheminformatics, and machine learning for life sciences.
Reviews

Kinnari Makwana
I learned how to use python for data retrieval, analysis and many more things.
Animesh Ray
I got a chance to know about application of python in life sciences
Sujal pawar
I learnBiopython and data analysis
ANASWARA C
I learned one of the main programne
Certificate

FAQ
Session Joining link will be send to your register email on the day of session start you can join session by clicking joining link.
All Session are evening sessions time of session is between 7:00 to 8:00 PM IST.
What about the refund of the course?
Please read refund policy in refund policy section page.
What Prerequisites knowledge required to join the course?
No, any short Prerequisites knowledge you required to join the course.